EMI Lab · arXiv preprint · 2026
GrainSpeechLess Context, More Detail
for Compact Speech Synthesis
GrainSpeech turns written text into speech using a small AI model.
Efficient Machine Intelligence Lab · TU Delft
* Corresponding author
01 / Audio demo
Hear the difference.
Choose a sentence. Listen to GrainSpeech,
then compare it with the original recording.
Choose a sentence
SENTENCE 01LJ015-0096
“whether representing real or fictitious shares does not appear; but they were certificates connected in some way with robson's long practiced frauds”
This work
Original recording
LJSpeech · human reference · 9.13 sCompare all models 12 acoustic variants · one shared sentence
GrainSpeech ablation
GrainSpeech (L1)
0.265M acoustic parameters · 8.60 sEfficientSpeech family
EfficientSpeech-Tiny
0.266M acoustic parameters · 8.53 sEfficientSpeech-Tiny (L1 + SSIM + GVar)
0.266M acoustic parameters · 8.59 sEfficientSpeech-Small
0.952M acoustic parameters · 8.36 sEfficientSpeech-Base
3.953M acoustic parameters · 8.58 sOther acoustic models
LightSpeech
1.771M acoustic parameters · 8.56 sSpeedySpeech
4.306M acoustic parameters · 8.17 sGrad-TTS
14.835M acoustic parameters · 8.38 sMatcha-TTS
18.204M acoustic parameters · 9.32 sNeMo MixerTTS
20.060M acoustic parameters · 8.77 sFastSpeech 2
35.159M acoustic parameters · 9.45 sSENTENCE 02LJ015-0187
“redpath passed away into the outer darkness of a penal colony, where he was still living a year or two back”
GrainSpeech
L1 + SSIM + GVar · 0.265M parameters · 6.44 sOriginal recording
LJSpeech · human reference · 7.57 sCompare all models 12 acoustic variants · one shared sentence
GrainSpeech ablation
GrainSpeech (L1)
0.265M acoustic parameters · 6.77 sEfficientSpeech family
EfficientSpeech-Tiny
0.266M acoustic parameters · 6.65 sEfficientSpeech-Tiny (L1 + SSIM + GVar)
0.266M acoustic parameters · 6.64 sEfficientSpeech-Small
0.952M acoustic parameters · 6.70 sEfficientSpeech-Base
3.953M acoustic parameters · 6.90 sOther acoustic models
LightSpeech
1.771M acoustic parameters · 6.65 sSpeedySpeech
4.306M acoustic parameters · 5.89 sGrad-TTS
14.835M acoustic parameters · 7.27 sMatcha-TTS
18.204M acoustic parameters · 7.70 sNeMo MixerTTS
20.060M acoustic parameters · 6.98 sFastSpeech 2
35.159M acoustic parameters · 7.57 sSENTENCE 03LJ002-0217
“the warden of the fleet at the commencement of the eighteenth century, are too well known to need more than a passing reference.”
GrainSpeech
L1 + SSIM + GVar · 0.265M parameters · 6.73 sOriginal recording
LJSpeech · human reference · 7.51 sCompare all models 12 acoustic variants · one shared sentence
GrainSpeech ablation
GrainSpeech (L1)
0.265M acoustic parameters · 7.04 sEfficientSpeech family
EfficientSpeech-Tiny
0.266M acoustic parameters · 6.56 sEfficientSpeech-Tiny (L1 + SSIM + GVar)
0.266M acoustic parameters · 6.71 sEfficientSpeech-Small
0.952M acoustic parameters · 6.59 sEfficientSpeech-Base
3.953M acoustic parameters · 6.99 sOther acoustic models
LightSpeech
1.771M acoustic parameters · 6.80 sSpeedySpeech
4.306M acoustic parameters · 6.49 sGrad-TTS
14.835M acoustic parameters · 6.84 sMatcha-TTS
18.204M acoustic parameters · 7.37 sNeMo MixerTTS
20.060M acoustic parameters · 7.11 sFastSpeech 2
35.159M acoustic parameters · 7.47 sSENTENCE 04LJ037-0157
“taken from oswald.”
GrainSpeech
L1 + SSIM + GVar · 0.265M parameters · 1.28 sOriginal recording
LJSpeech · human reference · 1.30 sCompare all models 12 acoustic variants · one shared sentence
GrainSpeech ablation
GrainSpeech (L1)
0.265M acoustic parameters · 1.15 sEfficientSpeech family
EfficientSpeech-Tiny
0.266M acoustic parameters · 1.23 sEfficientSpeech-Tiny (L1 + SSIM + GVar)
0.266M acoustic parameters · 1.17 sEfficientSpeech-Small
0.952M acoustic parameters · 1.20 sEfficientSpeech-Base
3.953M acoustic parameters · 1.18 sOther acoustic models
LightSpeech
1.771M acoustic parameters · 1.32 sSpeedySpeech
4.306M acoustic parameters · 1.20 sGrad-TTS
14.835M acoustic parameters · 1.32 sMatcha-TTS
18.204M acoustic parameters · 1.36 sNeMo MixerTTS
20.060M acoustic parameters · 1.34 sFastSpeech 2
35.159M acoustic parameters · 1.22 sSENTENCE 05LJ050-0062
“(c) who express or have expressed strong or violent anti-u.s. sentiments”
GrainSpeech
L1 + SSIM + GVar · 0.265M parameters · 4.60 sOriginal recording
LJSpeech · human reference · 6.29 sCompare all models 12 acoustic variants · one shared sentence
GrainSpeech ablation
GrainSpeech (L1)
0.265M acoustic parameters · 4.67 sEfficientSpeech family
EfficientSpeech-Tiny
0.266M acoustic parameters · 4.18 sEfficientSpeech-Tiny (L1 + SSIM + GVar)
0.266M acoustic parameters · 4.26 sEfficientSpeech-Small
0.952M acoustic parameters · 4.37 sEfficientSpeech-Base
3.953M acoustic parameters · 4.42 sOther acoustic models
LightSpeech
1.771M acoustic parameters · 4.83 sSpeedySpeech
4.306M acoustic parameters · 4.76 sGrad-TTS
14.835M acoustic parameters · 5.72 sMatcha-TTS
18.204M acoustic parameters · 6.18 sNeMo MixerTTS
20.060M acoustic parameters · 5.87 sFastSpeech 2
35.159M acoustic parameters · 5.34 sFive shared LJSpeech utterances. Every synthesized sample uses the same HiFi-GAN v2 vocoder; original recordings bypass it. Audio details & provenance
02 / The idea
Less context.
More acoustic detail.
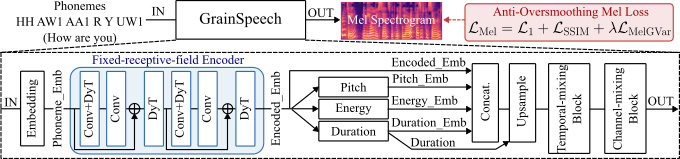
GrainSpeech explores how encoder context and Mel supervision affect compact speech synthesis. Its acoustic model has 264.8K parameters.
Focus the encoder
A fixed-receptive-field convolutional encoder uses local phoneme context to predict pitch, energy and duration.
Preserve fine structure
L1, SSIM and a Mel-specific gradient-variance objective supervise local detail along time and frequency.
03 / Results
Small enough for the edge.
264.8K
Acoustic model parameters
4.086
UTMOS on 128 LJSpeech utterances
17.9×
Real-time Mel generation on MCU
MCU result: A16W8 on STM32H747XI, 483.19 KiB peak SRAM. This measures acoustic-model inference; vocoding is excluded.
| Acoustic model | Parameters | UTMOS ↑ | WER (%) ↓ |
|---|---|---|---|
| GrainSpeech This work | 0.265M | 4.086 | 3.27 |
| EfficientSpeech-Tiny | 0.266M | 3.591 | 3.08 |
| MatchaTTS | 18.204M | 4.264 | 1.98 |
| MixerTTS | 20.060M | 4.087 | 1.80 |
Automatic metrics on LJSpeech. External models use their native training settings. See the paper for confidence intervals, spectral distortion and evaluation limitations.
04 / Open research
Read it.
Run it. Build on it.
The acoustic model, pretrained weights, inference and training code, and this paper website live in one repository.
Get started on GitHubCite GrainSpeech
@article{liang2026grainspeech,
  title = {GrainSpeech: Less Context, More Detail
           for Compact Speech Synthesis},
  author = {Liang, Zitao and Gao, Chang},
  journal = {arXiv preprint arXiv:2609.18856},
  year = {2026},
  doi = {10.48550/arXiv.2609.18856},
  url = {https://arxiv.org/abs/2609.18856}
}